Most small teams find out what server-side tracking is the hard way: an ad blocker update wipes out 20% of their Google Analytics numbers overnight, or Safari's Intelligent Tracking Prevention quietly starts deleting cookies after a week. Server-side tracking is the fix. Instead of sending data straight from a visitor's browser to a third party, you route it through a server you control first. No engineering degree required to understand why that matters, or to get a basic version running.
What server-side tracking actually means
Traditional analytics runs entirely client-side. A visitor loads your page, a tracking script fires in their browser, and that script sends data directly to Google, Meta, or whichever tool you use. The problem is that the browser is no longer a neutral messenger. Ad blockers strip out known tracking domains, browsers cap how long cookies survive, and privacy extensions block third-party requests by default.
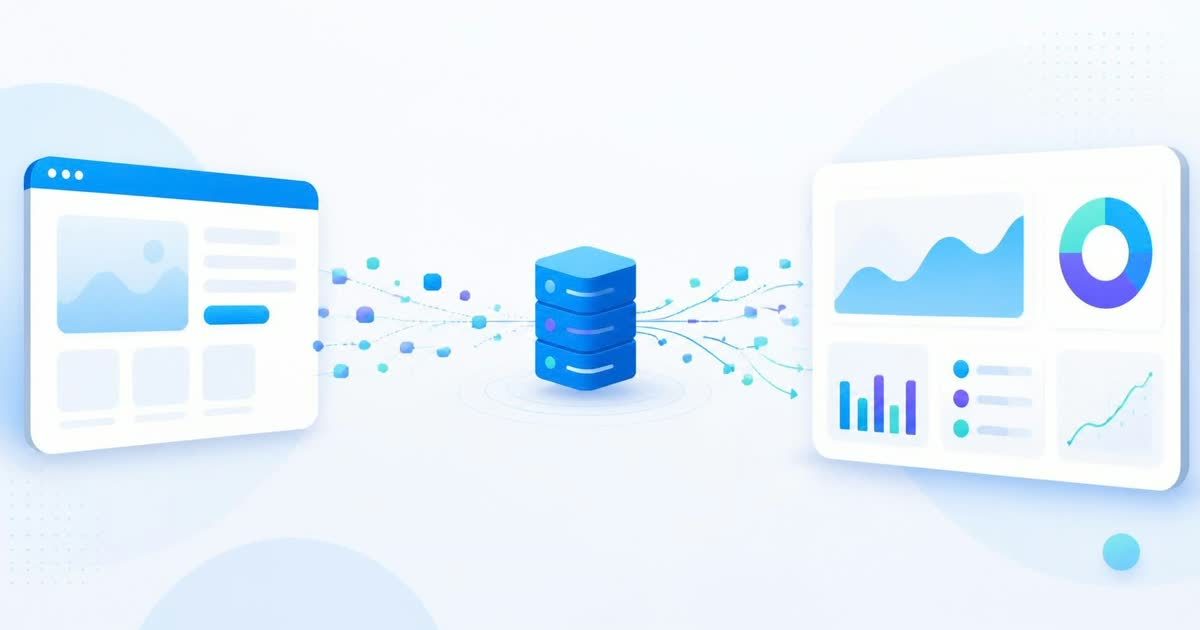
Server-side tracking moves the last step of that journey off the browser. The visitor's browser still sends an event, but it goes to a server endpoint you own (often a lightweight proxy or a tag manager server container) rather than directly to the analytics vendor. That server then forwards the data to whatever tools you actually use. To the browser, it looks like one request to your own domain. To your analytics dashboard, nothing changes.
Why it exists: browsers got stricter, not analytics
None of this changed because analytics vendors wanted more control. It changed because browsers tightened the rules. Safari's ITP limits first-party cookies set by scripts to seven days in many cases. Firefox blocks known trackers by default. Ad blockers like uBlock Origin maintain lists of tracking domains and silently drop any request that matches. A script loaded from google-analytics.com or facebook.net is an easy target. A request to yourdomain.com/collect is not, because blocking it would break your own site.
The result is a measurement gap that keeps growing. Industry estimates have long put ad blocker usage above 25% in some markets, and that number climbs higher on tech-savvy audiences, the kind of visitors who are often your best leads. If a quarter of your traffic never gets measured, every conversion rate, funnel report, and attribution model you run is working from a distorted sample.
The data you can't see isn't gone. It's just invisible to whoever is trying to make a decision from it.
What you gain by moving tracking server-side
- More accurate numbers. Requests to your own domain rarely get blocked, so you recover a meaningful chunk of the traffic ad blockers were hiding from you.
- Cookies that actually last. First-party cookies set server-side aren't subject to the same aggressive expiration rules browsers apply to client-set cookies, so returning-visitor and session data stays reliable longer.
- Faster page loads. Fewer third-party scripts means fewer render-blocking requests and fewer external domains your browser has to negotiate connections with.
- More control over what leaves your site. You decide exactly what data gets forwarded, to which tools, and in what shape, which makes privacy compliance easier to reason about instead of trusting a vendor's script to behave.
What it doesn't fix
Server-side tracking is not a workaround for consent requirements. If your visitors are in the EU and you're collecting personal data, you still need a lawful basis and, in most cases, a consent mechanism before you fire tracking events, server-side or not. It also doesn't make tracking invisible or untraceable. It changes where the request goes, not whether the visitor's activity is being recorded. Treat it as an accuracy and reliability upgrade, not a privacy shortcut, and you'll stay on the right side of both your users and regulators.
It's also not free of maintenance. A server-side setup means you now own a small piece of infrastructure: an endpoint that has to stay up, get monitored, and get updated when a downstream tool changes its API. For a two-person startup, that's a real cost to weigh against the accuracy gain.
How small teams actually set this up
You don't need to build a server-side pipeline from scratch. Google Tag Manager's server container is the most common entry point: you deploy a lightweight container (often on Cloud Run or a similar service), point your existing tags at it, and it forwards events to GA4, Meta, and other destinations while presenting a first-party face to the browser. It takes an afternoon to set up for a single site, not a sprint.
If that still sounds like more infrastructure than you want to manage, tools built around a first-party collection model from the start are worth a look. LeadFnF, for example, runs on a single lightweight script (about 3KB) and is built privacy-first from the ground up, so you get session replay, heatmaps, and funnel data without assembling a separate server-side pipeline just to keep your numbers accurate. Real-time reporting means you see what's happening on your site as it happens, not after a batch job catches up.
A simple starting checklist
- Audit how much of your current traffic is likely getting blocked. Compare your analytics sessions against your server access logs; a large gap is a signal.
- Decide whether you need a full server-side container or whether a tool with first-party collection built in solves the same problem with less upkeep.
- If you go the container route, start with your highest-value events (purchases, signups, key conversions) rather than migrating everything at once.
- Keep your consent banner and server-side setup in sync. A server-side pipeline that ignores consent choices is worse than no pipeline at all.
Server-side tracking sounds like a developer problem because it used to require one. Today, whether you assemble your own container or pick a tool that handles first-party collection natively, the goal is the same: see what's actually happening on your site instead of the filtered, ad-blocker-shrunk version of it. Try LeadFnF free for 14 days and see your real traffic without setting up a server yourself.